Researchers have built a formal grading system for deciding when enterprise AI deployments are actually ready to scale, not just look good in a demo.
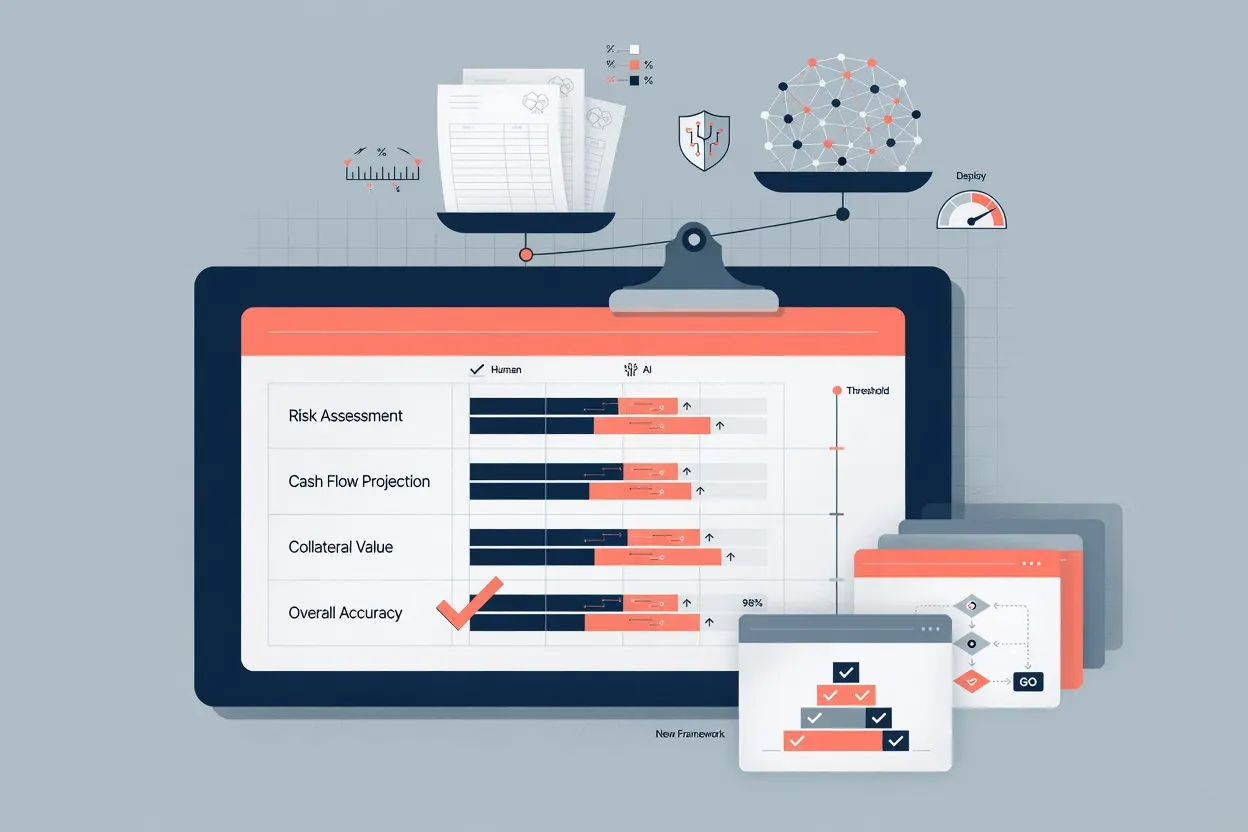
A new paper describes EnterpriseVal, an evaluation framework built for one specific gap: public benchmarks measure what a model can do in general, not whether a specific workflow is safe and reliable enough to run on a company's own data under its own controls. The system locks in every variable of a deployment, the model, prompts, retrieval setup, tools, guardrails and human oversight, then grades it against metrics covering accuracy, efficiency, reliability and oversight. A mix of blinded human experts and calibrated AI judges produces the scores, which feed a gate that sorts each use case into reject, conditional or scale. The authors piloted it on workflows inside a global bank. In credit-memo drafting, the best model hit 88% citation precision and a 1.6% hallucination rate, clearing gates set at 70% and 5%. In a procedure-rewriting task, the system cut estimated analyst refinement effort from 27.4 hours per document to 2.9.
This matters because most enterprise GenAI projects currently fail to show a measurable business effect, and a large share of agentic AI initiatives are expected to be cancelled outright. The paper's real argument is that this isn't mainly a model-quality problem, it's a measurement problem: companies keep asking benchmark questions when what they need are deployment-readiness answers.
A pilot at one bank is not proof the framework generalizes, but it is a more honest starting point than another leaderboard screenshot.